ادمج الإخراج متعدد الوسائط
اجمع المطالبات والمراجع البصرية معًا في ملخص إنتاج واحد مركّز.
حوّل المطالبات والمراجع البصرية إلى مشاهد سينمائية مترابطة مع صوت أصلي.
خطّط للهوية والحركة والمشاهد والصوت في ملخص واحد مركّز.
اجمع المطالبات والمراجع البصرية معًا في ملخص إنتاج واحد مركّز.
حدّد الافتتاح والحركة والانتقالات واللقطة الختامية كلحظات مترابطة.
أخرِج الأجواء أو الحوار أو الموسيقى جنبًا إلى جنب مع الحركة البصرية.
احمل الهوية والمظهر والصوت عبر المشاهد المترابطة.
حوّل الفكرة إلى فيديو قابل للتحكم عبر الفصل بين المدخلات والإخراج والمراجعة.
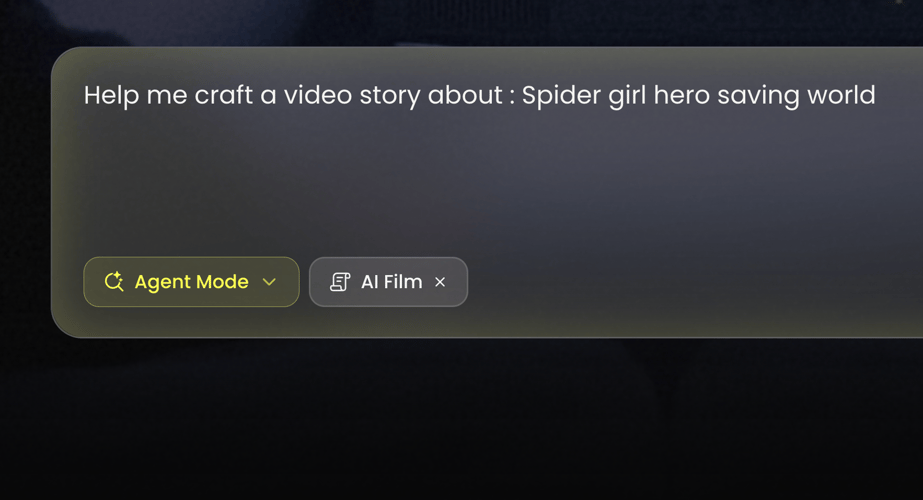 الخطوة 01
اختر Kling 3.0 في Buzzy. قرّر ما إذا كان المشهد يبدأ من نص أو صورة أو مجموعة أوسع من المراجع متعددة الوسائط المتاحة في مساحة العمل.
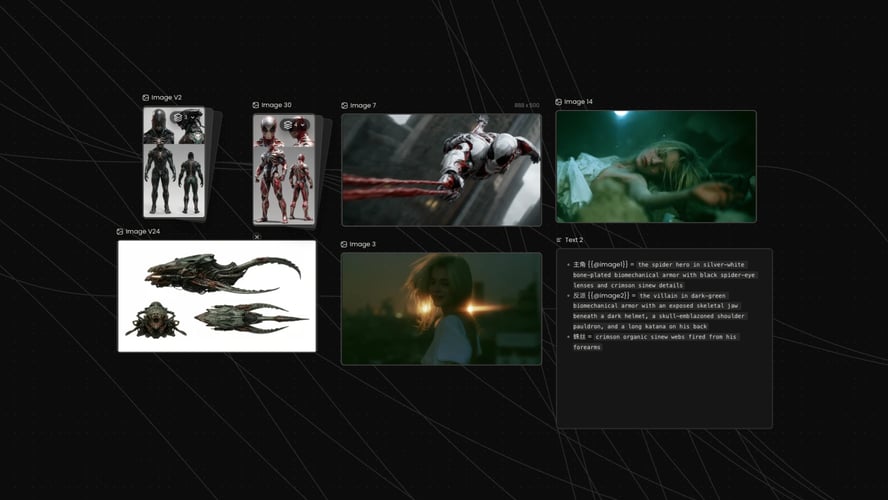 الخطوة 02
صِف ما يحدث، وليس فقط شكل الإطار. سمِّ الموضوع والهدف والمكان والحركة والكاميرا والصوت.
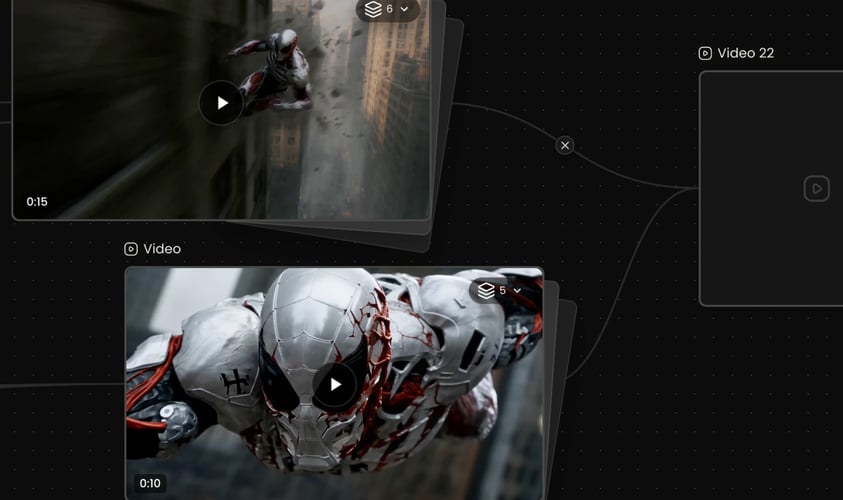 الخطوة 03
اختر الإعدادات المعروضة للنموذج النشط، ثم أنشئ وراجع النتيجة كاملة.
Buzzy
سمِّ الموضوع مبكرًا وحافظ على ثبات الأوصاف.
يجب أن يغيّر كل مشهد شيئًا ذا معنى.
صِف حركة الموضوع بشكل منفصل عن حركة الكاميرا.
اكتب الصوت الذي ينبغي أن يرافق الحركة.
اختر نسبة العرض وإعدادات الإخراج المعروضة في Buzzy وفقًا للوجهة.
احتفظ بالأجزاء التي نجحت واعزل التغيير التالي.
اجمع الإخراج المكتوب مع المدخلات البصرية ذات الصلة بدلًا من إجبار النموذج على استنتاج العنصر المهم.
خطّط للتسلسل كعدد صغير من اللقطات الهادفة.
طوّر مشهدًا مركّزًا بشخصية واضحة المعالم ودافع واضح وتحوّل بصري.
أنشئ كشفًا أو عرضًا توضيحيًا أو مشهدًا لنمط الحياة أو مفهوم حملة.
ابنِ خطافًا سريعًا وصراعًا وتغييرًا ونتيجة لمحتوى يركّز على الجوال.
نسّق الحركة والقطع والأجواء والإيقاع البصري حول فكرة موسيقية.
يجمع Buzzy أبرز نماذج الفيديو في مساحة عمل إبداعية واحدة مترابطة.
إجابات على أسئلة Kling 3.0 الشائعة.
Kling 3.0 هو أحدث سلسلة نماذج فيديو من KlingAI. يجمع بين تحليل التعليمات متعددة الوسائط، والتحكم في لوحة القصة، والصوت الأصلي، واتساق الهوية البصرية، واتساق نبرة الصوت، والانتقالات بين مشاهد متعددة.
اختر النموذج، وأضف أصول المدخلات ذات الصلة، واكتب مطالبة تصف الموضوع والحركة والمكان والكاميرا وترتيب المشاهد والصوت.
يدعم Kling 3.0 التحكم الموجّه بلوحة القصة والإنشاء المترابط لمشاهد متعددة. أبقِ التسلسل قصيرًا وهادفًا.
نعم. الصوت الأصلي جزء من نظام الإنشاء في النموذج. يمكنك تضمين سياق الحوار أو الأجواء أو المؤثرات أو الإخراج الموسيقي في الملخص.
صُمّم النموذج للحفاظ على الهوية البصرية ونبرة الصوت عبر المشاهد المترابطة. تبقى النتائج القوية معتمدة على مراجع متسقة وأوصاف ثابتة.
استخدمه للسرد القصير ومشاهد الشخصيات ومفاهيم المنتجات والمقاطع الاجتماعية والتسلسلات ذات العلامة التجارية وأفكار الأداء والمرئيات التي تقودها الموسيقى واختبارات لوحة القصة.
اكتب الموضوع والحركة أولًا، ثم أضف ترتيب المشاهد والمكان والكاميرا والأسلوب والصوت. افصل حركة الموضوع عن حركة الكاميرا.
يعرض Buzzy في مساحة العمل إمكانية الإنشاء الحالية والأرصدة وإعدادات النموذج.
Create a video from an idea, visual reference, or planned sequence without separating every creative decision into a different tool. Kling 3.0 combines multimodal instruction understanding, storyboard-level control, connected scenes, and native audio generation. Buzzy gives you one workspace for turning those capabilities into a clear production brief. Start by deciding what must remain consistent: a character, product, location, visual style, voice, or action. Then describe how the scene develops over time. Kling 3.0 is especially useful when the result needs more than generic motion—when identity, pacing, transitions, and sound must serve the same story.
Combine written direction with relevant visual inputs instead of forcing the model to infer which element matters. You can define subject identity, scene context, action, camera behavior, and mood in a connected request. Kling 3.0 parses multimodal instructions across creation tasks, making it suitable for workflows that begin with more than text alone.
Plan a sequence as a small number of purposeful shots. Establish the opening, describe the transition or action, and define the closing image. Kling 3.0 supports storyboard-oriented direction and multi-scene generation, so creators can think in beats rather than treating every clip as an unrelated experiment.
Sound can reinforce place, pace, and emotional tone. Add dialogue context, ambience, effects, or music direction when audio belongs to the concept. Kling 3.0 includes native audio generation, helping the visual and sound evolve from the same brief. Review generated speech and synchronization carefully because generative output is not a guarantee of exact delivery.
When a concept depends on a recognizable character, consistent identity matters across shots. Kling 3.0 is designed to maintain visual identity and vocal tone through connected scenes. Clear references and a stable character description reduce ambiguity, while a focused sequence prevents unrelated style shifts from competing with the subject.
Select Kling 3.0 in Buzzy. Decide whether the scene starts from text, an image, or a broader set of multimodal references available in the workspace. Use the fewest assets needed to establish the subject and style. If two references communicate conflicting identities or environments, resolve that conflict before generating.
Describe what happens, not just what the frame looks like. Name the subject, goal, setting, action, camera, and sound. For several scenes, write a simple order: opening state, change, transition, and final state. Kling 3.0 can work with sophisticated instructions, but the model still benefits from a clear hierarchy.
Choose the settings shown for the active model, generate, and review the complete result. Check subject identity, action order, camera continuity, transitions, audio, and final framing. Revise one category at a time. If character identity is strong but the pacing is wrong, preserve the identity description and change only the timing instructions.
Name the subject early and keep descriptors stable. For a person or character, focus on a few durable details rather than a long costume inventory. For a product, identify the shape, material, color, and branding elements that must remain recognizable. Kling 3.0 needs consistent guidance to preserve the same visual anchor across a sequence.
Every scene should change something meaningful. A character enters, an object transforms, the camera reveals a new environment, or a product moves from context to close-up. Avoid adding scenes simply to make the video feel larger. Storyboard control works best when the sequence has a readable cause and effect.
Describe subject motion separately from camera motion. “The runner turns toward the doorway while the camera tracks backward” is easier to interpret than a stack of cinematic labels. Kling 3.0 supports fine creative direction, but clarity still beats jargon. Use one primary camera action per shot whenever possible.
Write the sound that should accompany the action. If dialogue matters, specify the speaker, emotional delivery, and short intended line. If ambience matters more, describe the environment and timing. Native audio can strengthen the result, but always review speech, vocal identity, timing, and content before publishing.
Choose the ratio and output settings displayed in Buzzy according to the destination. Vertical composition should keep faces, products, and action inside a mobile-safe frame. Landscape composition can create more environmental context. Kling 3.0 prompts should reflect the selected frame rather than relying on later cropping.
Keep the parts that worked and isolate the next change. Replacing the entire prompt after every result makes it harder to understand which instruction improved the output. Save a stable subject and scene description, then refine pacing, camera, transition, or audio in a controlled next pass.
Combine written direction with relevant visual inputs instead of forcing the model to infer which element matters. You can define subject identity, scene context, action, camera behavior, and mood in a connected request. Kling 3.0 parses multimodal instructions across creation tasks, making it suitable for workflows that begin with more than text alone.
Plan a sequence as a small number of purposeful shots. Establish the opening, describe the transition or action, and define the closing image. Kling 3.0 supports storyboard-oriented direction and multi-scene generation, so creators can think in beats rather than treating every clip as an unrelated experiment.
Develop a compact scene with a recognizable character, clear motivation, and visual turn. Use references when identity is essential, then describe the emotional and physical progression. Connected scenes can move from setup to reaction without abandoning the same visual world.
Create a reveal, demonstration, lifestyle scene, or campaign concept. Identify the product features that must remain accurate, then use camera and environment to build attention. Kling 3.0 can support several related shots, allowing a product to move from context to detail within one planned sequence.
Build a quick hook, conflict, change, and payoff for mobile-first content. Keep the action readable without sound, then use native audio to deepen the result. A strong first frame and concise visual premise matter more than unnecessary complexity.
Coordinate movement, cuts, ambience, and visual rhythm around a musical idea. Describe the relationship between motion and sound instead of merely requesting “cinematic music.” Kling 3.0 works best when the audio direction has a role in the scene’s progression.
Kling 3.0 is the latest KlingAI video model series. It combines multimodal instruction parsing, storyboard control, native audio, visual identity consistency, vocal tone consistency, and multi-scene transitions. On Buzzy, those capabilities can be used through a focused AI video generation workflow.
Select the model, add the relevant input assets, and write a prompt that describes the subject, action, setting, camera, scene order, and audio. Choose the available ratio and output settings, generate, then review identity, motion, transitions, and sound before refining.
Kling 3.0 supports storyboard-oriented control and connected multi-scene generation. Keep the sequence short and purposeful. Define the opening, the change between scenes, and the closing state so each part advances the same concept.
Yes. Native audio is part of the model’s creation system. You can include dialogue context, ambience, effects, or music direction in the brief. Generated audio can vary, so review wording, voice, timing, and synchronization before using the clip.
The model is designed to maintain visual identity and vocal tone across connected scenes. Strong results still depend on coherent references and stable descriptions. Avoid changing defining character details between shots unless transformation is the point of the story.
Use it for short narratives, character scenes, product concepts, social clips, branded sequences, performance ideas, music-led visuals, and storyboard tests. Choose a concept where multimodal input, continuity, or native audio provides a real creative advantage.
Write the subject and action first, then add scene order, setting, camera, style, and audio. Separate subject movement from camera movement. For a sequence, use time-based language so the model understands what happens first, what changes, and how the final shot resolves.
Buzzy displays the current generation access, credits, and model settings in the workspace. Availability and pricing can change, so use the active interface as the source of truth rather than assuming a permanent free allowance.
اختر قصة واحدة، ومرتكزًا بصريًا متسقًا واحدًا، وتسلسلًا واضحًا واحدًا.