Dirige con multiples tipos de medios
Usa texto, imagenes, video y audio para comunicar cada parte de la idea.
Crea video y audio conectados a partir de referencias de texto, imagenes, video y sonido.
Guia el movimiento, la camara, las escenas y el sonido desde un unico brief multimodal.
Usa texto, imagenes, video y audio para comunicar cada parte de la idea.
Planifica una apertura, una progresion, una transicion y un final con sonido sincronizado.
Separa la accion del sujeto del movimiento de camara para una direccion fisica mas clara.
Continua o reformula una escena manteniendo estables sus senales visuales esenciales.
Construye el brief en tres pasos para que cada entrada e instruccion tenga una funcion clara.
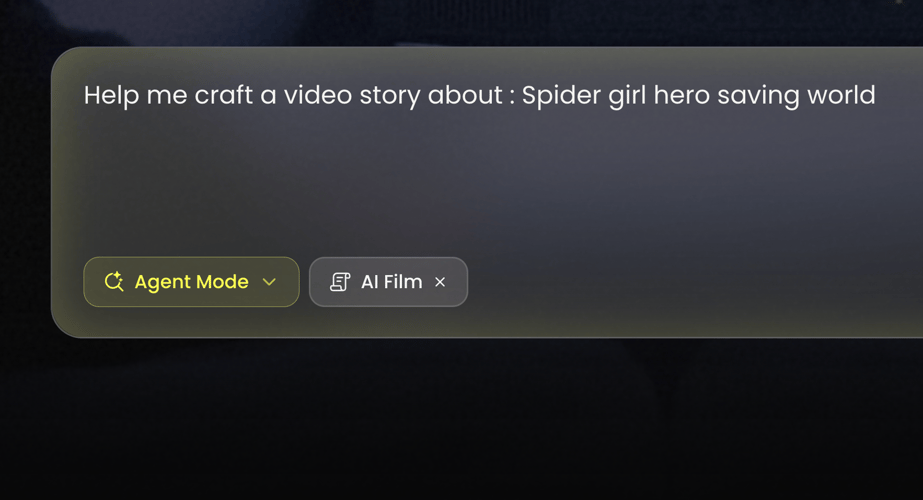 PASO 01
Elige Seedance 2.0 en Buzzy y decide si el concepto empieza solo con texto o necesita referencias de imagen, video o audio.
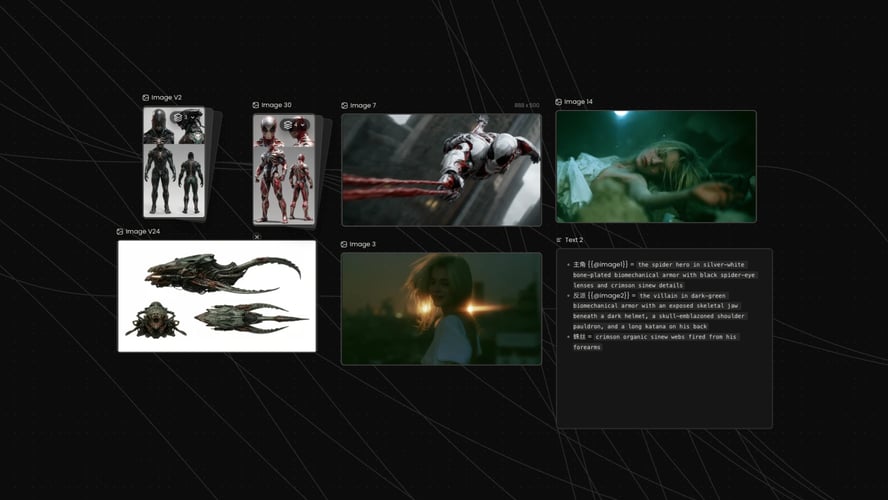 PASO 02
Escribe la accion en orden. Indica que ocurre primero, como cambia la escena, que hace la camara y como se resuelve el clip.
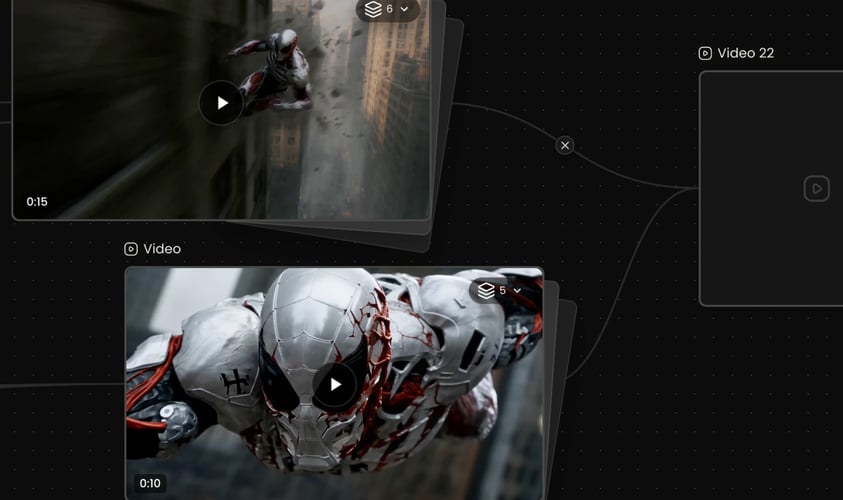 PASO 03
Elige los ajustes disponibles en el espacio de trabajo de Buzzy, genera y mira el resultado completo con sonido.
Buzzy
Indica al modelo que debe influir cada recurso.
Usa descripciones estables y referencias coherentes. Nombra los rasgos definitorios que deben seguir siendo reconocibles entre tomas.
Escribe las acciones con un inicio y un resultado legibles.
Elige un comportamiento de camara principal para cada toma.
Divide la secuencia en unos pocos momentos con un sujeto y un lenguaje visual compartidos.
Describe la ambientacion, los efectos, el contexto de dialogo o la musica en relacion con la linea de tiempo visual.
Seedance 2.0 admite generacion corta de varias tomas, con la duracion, la relacion de aspecto y las opciones de salida activas mostradas dentro de Buzzy.
Revisa el clip completo y aisla el siguiente cambio.
Construye un breve planteamiento, accion y resolucion en torno a un personaje o evento.
Crea un reveal, una demostracion, una escena de estilo de vida o un storyboard de campana.
Usa el audio para guiar el ritmo, el movimiento y la atmosfera. Explica que movimientos deben responder al ritmo y donde cambia la escena. Seedance 2.
Diseña un gancho inmediato, una transformacion legible o una secuencia de accion compacta para un formato social elegido.
Buzzy reune multiples modelos de video y flujos de trabajo creativos en un solo lugar.
Respuestas a preguntas comunes sobre Seedance 2.0.
Seedance 2.0 es el modelo de video con IA multimodal de ByteDance Seed.
Selecciona el modelo, anade las referencias relevantes y escribe la direccion de sujeto, secuencia, movimiento, camara y sonido.
Si. El audio puede formar parte de la entrada multimodal y guiar el ritmo, la atmosfera o la direccion de sonido. Explica como se relaciona el audio con la secuencia visual.
Si. El modelo admite generacion de audio y video de varias tomas. Planifica una secuencia concisa con apertura, progresion y resolucion. Manten estables los sujetos y el estilo visual salvo que el prompt introduzca un cambio de forma intencionada.
El modelo admite entradas de texto, imagen, video y audio. Usa cada referencia con un proposito definido y manten el conjunto coherente.
Seedance 2.0 esta disenado para el movimiento complejo, el realismo fisico y el control.
El modelo admite flujos de edicion y ampliacion de video. Aporta el contexto de origen, indica que debe permanecer sin cambios y describe la nueva accion o edicion visible.
Buzzy muestra el acceso actual, la disponibilidad del modelo, los requisitos de creditos y los ajustes dentro del espacio de trabajo.
Turn text, images, video, and audio references into a connected video sequence. Seedance 2.0 is built around unified multimodal audio-video generation, giving creators a way to direct subject motion, camera behavior, scene structure, and sound in the same brief. Buzzy places that capability inside a focused creative workspace. Start with the idea you need to communicate and the source material that protects it. A text prompt can create a new scene, while visual or audio references can guide identity, motion, framing, rhythm, and atmosphere. Seedance 2.0 is especially useful when the concept needs controllable movement and synchronized sound across more than one shot.
Use the medium that best communicates each part of the idea. Text explains the objective and sequence. Images can establish characters, products, compositions, or style. Video can provide motion and camera context. Audio can guide rhythm, ambience, or the intended soundscape. Seedance 2.0 reasons across these inputs as parts of one creative request.
Plan several connected shots instead of generating unrelated clips. Define the opening, progression, transition, and ending. Seedance 2.0 supports multi-shot output with synchronized audio, allowing the story and sound to develop together. Keep the sequence concise enough that every shot has a distinct purpose.
Describe how subjects move through the environment and how the camera responds. Seedance 2.0 is designed for complex motion, physical accuracy, realism, and controllability. Separate subject action from camera action, and state the timing when one movement depends on another.
Use source material to continue a scene, reshape an action, or develop a new version that remains connected to the original. Seedance 2.0 supports editing and extension workflows. Explain what must stay stable and identify the requested change instead of asking the model to reinvent the entire sequence.
Choose Seedance 2.0 in Buzzy and decide whether the concept begins with text alone or needs image, video, or audio references. Use only assets that belong to the same creative direction. Identify the core subject, visual anchor, or sound cue that should remain recognizable throughout the sequence.
Write the action in order. State what happens first, how the scene changes, what the camera does, and how the clip resolves. Add sound direction that belongs to the same timeline. Seedance 2.0 can combine multiple modalities, but the prompt should still make their relationships explicit.
Choose the settings available in the Buzzy workspace, generate, and watch the full result with sound. Review subject consistency, motion quality, camera continuity, transitions, and audio. Preserve the parts that worked and revise the most important issue. Controlled iteration is easier to evaluate than replacing the whole brief after every take.
Tell the model what each asset should influence. One image may define a person, another a location, a video may provide a motion pattern, and audio may establish pacing. Seedance 2.0 supports multiple reference types, but a clear hierarchy prevents one asset from unintentionally overriding another.
Use stable descriptions and cohesive references. Name the defining features that must remain recognizable across shots. If the subject changes clothing, location, or state during the sequence, describe when that transformation occurs. Consistency improves when change is deliberate rather than implied.
Write actions with a readable beginning and result. Explain contact, weight, direction, and timing when they matter: a hand lifts an object, fabric reacts to movement, water splashes after impact, or a vehicle changes speed before turning. Seedance 2.0 is designed for realistic and controllable motion, but the brief should still be physically understandable.
Choose one primary camera behavior for each shot. A tracking move follows action, a push-in directs attention, a reveal changes context, and a static view makes transformation easier to see. Do not stack conflicting instructions. The camera should help the audience understand the moment.
Divide the sequence into a few beats with a shared subject and visual language. Each shot should introduce information or advance the action. Use transition language when the connection matters. Seedance 2.0 can produce multi-shot video, but structure still comes from the brief.
Describe ambience, effects, dialogue context, or music in relation to the visual timeline. The model supports audio-video joint generation and advanced audio output, but generated sound requires review. Check speech, synchronization, loudness, and whether audio matches the environment before publishing.
Seedance 2.0 supports short multi-shot generation, with active duration, ratio, and output options shown inside Buzzy. Choose the format for the final destination before writing the composition. A vertical clip needs tighter subject framing than a landscape sequence.
Review the complete clip and isolate the next change. If motion works but the audio is wrong, keep the visual direction stable and revise the sound. If the subject is consistent but the transition feels abrupt, change the shot connection. One controlled decision per pass makes improvement easier to trace.
Build a short setup, action, and resolution around one character or event. Use images to define identity, video references for motion, and text to explain how the shots connect. Seedance 2.0 can support the sequence as one audio-visual idea rather than a set of disconnected clips.
Create a reveal, demonstration, lifestyle scene, or campaign storyboard. Preserve the product’s defining visual details and describe how it moves through the sequence. Use camera changes to reveal context or features, while sound supports the product moment without overwhelming it.
Use audio to guide pacing, movement, and atmosphere. Explain which motions should respond to the rhythm and where the scene changes. Seedance 2.0 can work with audio references and joint generation, making it useful for performance concepts, music-led visuals, and rhythmic transitions.
Design an immediate hook, a readable transformation, or a compact action sequence for a chosen social format. Keep the primary subject visible on a small screen and make the first beat clear. References can guide style, but the prompt should still define the intended story or change.
Seedance 2.0 is ByteDance Seed’s multimodal AI video model. It accepts text, image, audio, and video inputs and is designed for unified audio-video generation, complex motion, controllability, multi-shot sequences, editing, and extension.
Select the model, add the relevant references, and write the subject, sequence, motion, camera, and sound direction. Choose the available format and duration settings, generate the result, and review visual continuity and audio together before making a focused revision.
Yes. Audio can be part of the multimodal input and can guide rhythm, atmosphere, or sound direction. Explain how the audio relates to the visual sequence. Review the generated sound and synchronization because output can vary from the intended reference.
Yes. The model supports multi-shot audio-video generation. Plan a concise sequence with an opening, progression, and resolution. Keep subjects and visual style stable unless the prompt intentionally introduces a change.
The model supports text, image, video, and audio inputs. Use each reference for a defined purpose and keep the set coherent. The exact upload limits and options available to you should be taken from the active Buzzy workspace.
Seedance 2.0 is designed for complex movement, physical realism, and control. Better prompts still explain the action in time: what begins the motion, how the subject and environment respond, what the camera does, and where the action ends.
The model supports video editing and extension workflows. Provide the source context, state what must remain unchanged, and describe the new action or visible edit. Keep each request focused so the result can be compared directly with the original.
Buzzy displays current access, model availability, credit requirements, and settings inside the workspace. These conditions can change, so use the active interface as the source of truth rather than assuming a permanent free tier.
Lleva una idea audiovisual clara a Buzzy, elige las referencias que protegen sus elementos mas importantes y describe la secuencia de forma directa.