멀티모달 연출 결합
프롬프트와 시각적 레퍼런스를 하나의 집중된 제작 브리프로 모으세요.
프롬프트와 시각적 레퍼런스를 네이티브 오디오가 포함된 연결된 시네마틱 장면으로 바꾸세요.
정체성, 모션, 장면, 사운드를 하나의 집중된 브리프에서 계획하세요.
프롬프트와 시각적 레퍼런스를 하나의 집중된 제작 브리프로 모으세요.
오프닝, 액션, 전환, 마무리 프레임을 연결된 비트로 정의하세요.
시각적 액션과 함께 분위기, 대사, 음악을 연출하세요.
연결된 장면 전반에 걸쳐 정체성, 외형, 목소리를 이어가세요.
입력, 연출, 검토를 분리하여 콘셉트를 제어 가능한 영상으로 바꾸세요.
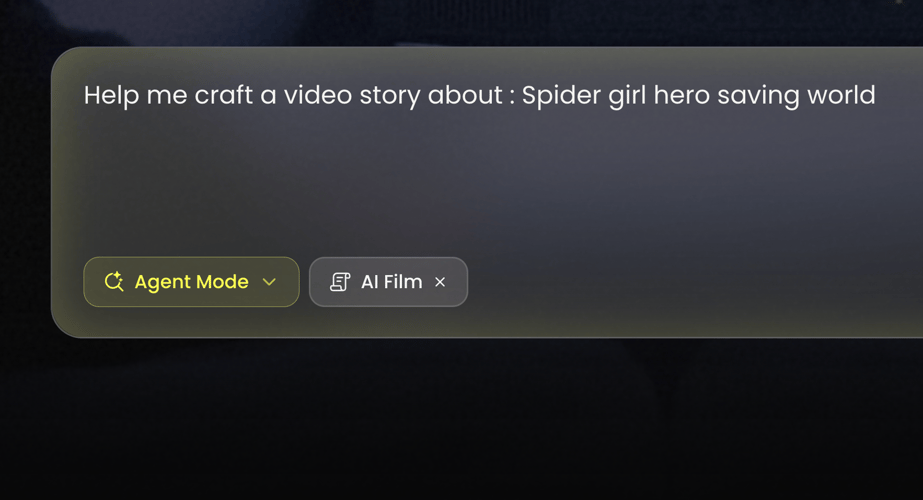 단계 01
Buzzy에서 Kling 3.0을 선택하세요. 장면을 텍스트, 이미지, 또는 워크스페이스에서 사용할 수 있는 더 폭넓은 멀티모달 레퍼런스 중 무엇으로 시작할지 결정하세요.
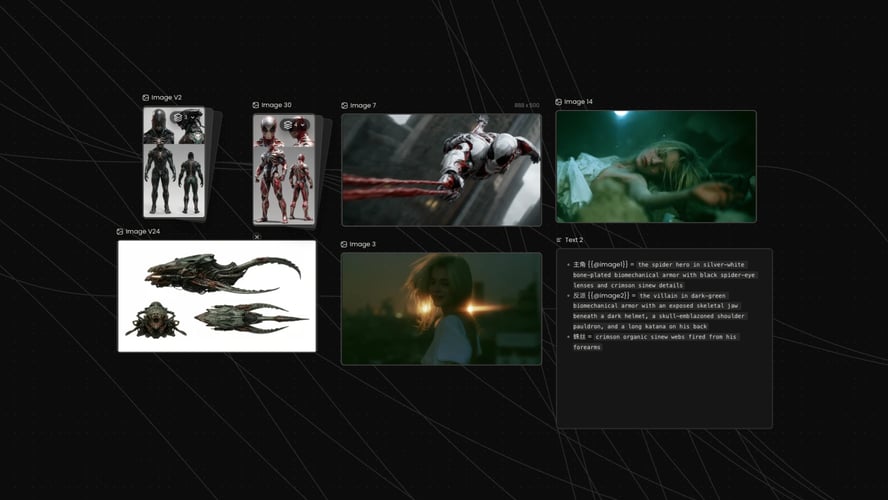 단계 02
프레임이 어떻게 보이는지뿐 아니라 무슨 일이 일어나는지 설명하세요. 대상, 목표, 배경, 액션, 카메라, 사운드를 명시하세요.
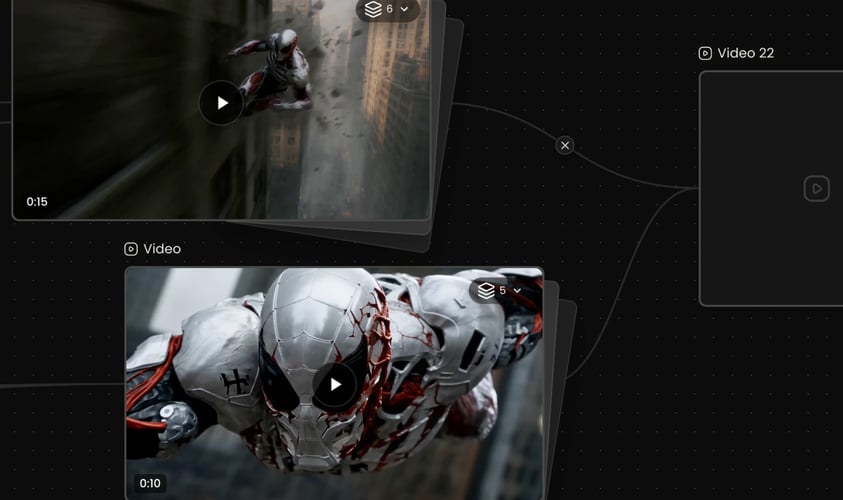 단계 03
활성 모델에 표시된 설정을 선택하고 생성한 뒤 전체 결과를 검토하세요.
Buzzy
대상을 일찍 지정하고 묘사를 일관되게 유지하세요.
각 장면은 의미 있는 무언가를 바꿔야 합니다.
대상의 움직임을 카메라의 움직임과 별도로 설명하세요.
액션에 어울리는 사운드를 작성하세요.
목적지에 따라 Buzzy에 표시되는 화면 비율과 출력 설정을 선택하세요.
효과가 있었던 부분은 유지하고 다음 변경 사항을 분리하세요.
어떤 요소가 중요한지 모델이 추측하게 하는 대신, 작성된 연출을 관련 시각적 입력과 결합하세요.
시퀀스를 목적이 분명한 소수의 샷으로 계획하세요.
알아볼 수 있는 캐릭터, 명확한 동기, 시각적 전환을 갖춘 압축된 장면을 전개하세요.
공개, 시연, 라이프스타일 장면 또는 캠페인 콘셉트를 만드세요.
모바일 우선 콘텐츠를 위해 빠른 훅, 갈등, 변화, 마무리를 구성하세요.
음악 아이디어를 중심으로 움직임, 컷, 분위기, 시각적 리듬을 조율하세요.
Buzzy는 주요 영상 모델을 하나의 연결된 크리에이티브 워크스페이스로 모읍니다.
일반적인 Kling 3.0 질문에 대한 답변.
Kling 3.0은 KlingAI의 최신 영상 모델 시리즈입니다. 멀티모달 지시 분석, 스토리보드 제어, 네이티브 오디오, 시각적 정체성 일관성, 음색 일관성, 다중 장면 전환을 결합합니다.
모델을 선택하고 관련 입력 자산을 추가한 뒤, 대상, 액션, 배경, 카메라, 장면 순서, 오디오를 설명하는 프롬프트를 작성하세요.
Kling 3.0은 스토리보드 중심 제어와 연결된 다중 장면 생성을 지원합니다. 시퀀스는 짧고 목적이 분명하게 유지하세요.
네. 네이티브 오디오는 모델 생성 시스템의 일부입니다. 브리프에 대사 맥락, 분위기, 효과음 또는 음악 연출을 포함할 수 있습니다.
이 모델은 연결된 장면 전반에 걸쳐 시각적 정체성과 음색을 유지하도록 설계되었습니다. 뛰어난 결과는 여전히 일관된 레퍼런스와 안정적인 묘사에 달려 있습니다.
짧은 내러티브, 캐릭터 장면, 제품 콘셉트, 소셜 클립, 브랜드 시퀀스, 퍼포먼스 아이디어, 음악 중심 비주얼, 스토리보드 테스트에 사용하세요.
먼저 대상과 액션을 쓰고, 그다음 장면 순서, 배경, 카메라, 스타일, 오디오를 추가하세요. 대상의 움직임과 카메라의 움직임을 분리하세요.
Buzzy는 워크스페이스에 현재 생성 액세스, 크레딧, 모델 설정을 표시합니다.
Create a video from an idea, visual reference, or planned sequence without separating every creative decision into a different tool. Kling 3.0 combines multimodal instruction understanding, storyboard-level control, connected scenes, and native audio generation. Buzzy gives you one workspace for turning those capabilities into a clear production brief. Start by deciding what must remain consistent: a character, product, location, visual style, voice, or action. Then describe how the scene develops over time. Kling 3.0 is especially useful when the result needs more than generic motion—when identity, pacing, transitions, and sound must serve the same story.
Combine written direction with relevant visual inputs instead of forcing the model to infer which element matters. You can define subject identity, scene context, action, camera behavior, and mood in a connected request. Kling 3.0 parses multimodal instructions across creation tasks, making it suitable for workflows that begin with more than text alone.
Plan a sequence as a small number of purposeful shots. Establish the opening, describe the transition or action, and define the closing image. Kling 3.0 supports storyboard-oriented direction and multi-scene generation, so creators can think in beats rather than treating every clip as an unrelated experiment.
Sound can reinforce place, pace, and emotional tone. Add dialogue context, ambience, effects, or music direction when audio belongs to the concept. Kling 3.0 includes native audio generation, helping the visual and sound evolve from the same brief. Review generated speech and synchronization carefully because generative output is not a guarantee of exact delivery.
When a concept depends on a recognizable character, consistent identity matters across shots. Kling 3.0 is designed to maintain visual identity and vocal tone through connected scenes. Clear references and a stable character description reduce ambiguity, while a focused sequence prevents unrelated style shifts from competing with the subject.
Select Kling 3.0 in Buzzy. Decide whether the scene starts from text, an image, or a broader set of multimodal references available in the workspace. Use the fewest assets needed to establish the subject and style. If two references communicate conflicting identities or environments, resolve that conflict before generating.
Describe what happens, not just what the frame looks like. Name the subject, goal, setting, action, camera, and sound. For several scenes, write a simple order: opening state, change, transition, and final state. Kling 3.0 can work with sophisticated instructions, but the model still benefits from a clear hierarchy.
Choose the settings shown for the active model, generate, and review the complete result. Check subject identity, action order, camera continuity, transitions, audio, and final framing. Revise one category at a time. If character identity is strong but the pacing is wrong, preserve the identity description and change only the timing instructions.
Name the subject early and keep descriptors stable. For a person or character, focus on a few durable details rather than a long costume inventory. For a product, identify the shape, material, color, and branding elements that must remain recognizable. Kling 3.0 needs consistent guidance to preserve the same visual anchor across a sequence.
Every scene should change something meaningful. A character enters, an object transforms, the camera reveals a new environment, or a product moves from context to close-up. Avoid adding scenes simply to make the video feel larger. Storyboard control works best when the sequence has a readable cause and effect.
Describe subject motion separately from camera motion. “The runner turns toward the doorway while the camera tracks backward” is easier to interpret than a stack of cinematic labels. Kling 3.0 supports fine creative direction, but clarity still beats jargon. Use one primary camera action per shot whenever possible.
Write the sound that should accompany the action. If dialogue matters, specify the speaker, emotional delivery, and short intended line. If ambience matters more, describe the environment and timing. Native audio can strengthen the result, but always review speech, vocal identity, timing, and content before publishing.
Choose the ratio and output settings displayed in Buzzy according to the destination. Vertical composition should keep faces, products, and action inside a mobile-safe frame. Landscape composition can create more environmental context. Kling 3.0 prompts should reflect the selected frame rather than relying on later cropping.
Keep the parts that worked and isolate the next change. Replacing the entire prompt after every result makes it harder to understand which instruction improved the output. Save a stable subject and scene description, then refine pacing, camera, transition, or audio in a controlled next pass.
Combine written direction with relevant visual inputs instead of forcing the model to infer which element matters. You can define subject identity, scene context, action, camera behavior, and mood in a connected request. Kling 3.0 parses multimodal instructions across creation tasks, making it suitable for workflows that begin with more than text alone.
Plan a sequence as a small number of purposeful shots. Establish the opening, describe the transition or action, and define the closing image. Kling 3.0 supports storyboard-oriented direction and multi-scene generation, so creators can think in beats rather than treating every clip as an unrelated experiment.
Develop a compact scene with a recognizable character, clear motivation, and visual turn. Use references when identity is essential, then describe the emotional and physical progression. Connected scenes can move from setup to reaction without abandoning the same visual world.
Create a reveal, demonstration, lifestyle scene, or campaign concept. Identify the product features that must remain accurate, then use camera and environment to build attention. Kling 3.0 can support several related shots, allowing a product to move from context to detail within one planned sequence.
Build a quick hook, conflict, change, and payoff for mobile-first content. Keep the action readable without sound, then use native audio to deepen the result. A strong first frame and concise visual premise matter more than unnecessary complexity.
Coordinate movement, cuts, ambience, and visual rhythm around a musical idea. Describe the relationship between motion and sound instead of merely requesting “cinematic music.” Kling 3.0 works best when the audio direction has a role in the scene’s progression.
Kling 3.0 is the latest KlingAI video model series. It combines multimodal instruction parsing, storyboard control, native audio, visual identity consistency, vocal tone consistency, and multi-scene transitions. On Buzzy, those capabilities can be used through a focused AI video generation workflow.
Select the model, add the relevant input assets, and write a prompt that describes the subject, action, setting, camera, scene order, and audio. Choose the available ratio and output settings, generate, then review identity, motion, transitions, and sound before refining.
Kling 3.0 supports storyboard-oriented control and connected multi-scene generation. Keep the sequence short and purposeful. Define the opening, the change between scenes, and the closing state so each part advances the same concept.
Yes. Native audio is part of the model’s creation system. You can include dialogue context, ambience, effects, or music direction in the brief. Generated audio can vary, so review wording, voice, timing, and synchronization before using the clip.
The model is designed to maintain visual identity and vocal tone across connected scenes. Strong results still depend on coherent references and stable descriptions. Avoid changing defining character details between shots unless transformation is the point of the story.
Use it for short narratives, character scenes, product concepts, social clips, branded sequences, performance ideas, music-led visuals, and storyboard tests. Choose a concept where multimodal input, continuity, or native audio provides a real creative advantage.
Write the subject and action first, then add scene order, setting, camera, style, and audio. Separate subject movement from camera movement. For a sequence, use time-based language so the model understands what happens first, what changes, and how the final shot resolves.
Buzzy displays the current generation access, credits, and model settings in the workspace. Availability and pricing can change, so use the active interface as the source of truth rather than assuming a permanent free allowance.
하나의 이야기, 하나의 일관된 시각적 앵커, 하나의 명확한 시퀀스를 선택하세요.