여러 미디어 유형으로 연출
텍스트, 이미지, 영상, 오디오를 사용해 아이디어의 각 부분을 전달하세요.
텍스트, 이미지, 영상, 사운드 레퍼런스로 서로 연결된 영상과 오디오를 만듭니다.
하나의 멀티모달 브리프에서 모션, 카메라, 장면, 사운드를 연출하세요.
텍스트, 이미지, 영상, 오디오를 사용해 아이디어의 각 부분을 전달하세요.
동기화된 사운드와 함께 오프닝, 전개, 전환, 엔딩을 계획하세요.
더 명확한 물리적 연출을 위해 피사체의 동작과 카메라 움직임을 분리하세요.
핵심 시각적 단서를 안정적으로 유지하면서 장면을 이어가거나 재구성하세요.
모든 입력과 지시에 명확한 역할을 부여하도록 세 단계로 브리프를 구성하세요.
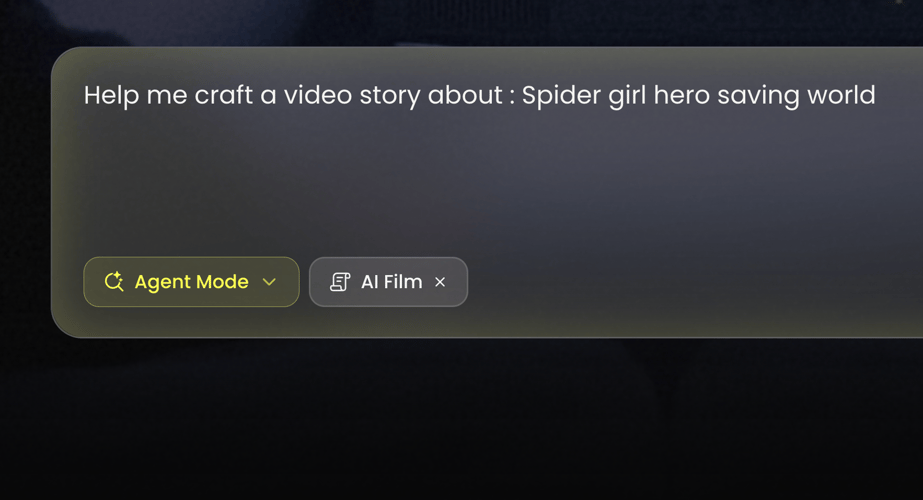 단계 01
Buzzy에서 Seedance 2.0을 선택하고, 콘셉트를 텍스트만으로 시작할지 이미지, 영상, 오디오 레퍼런스가 필요한지 결정하세요.
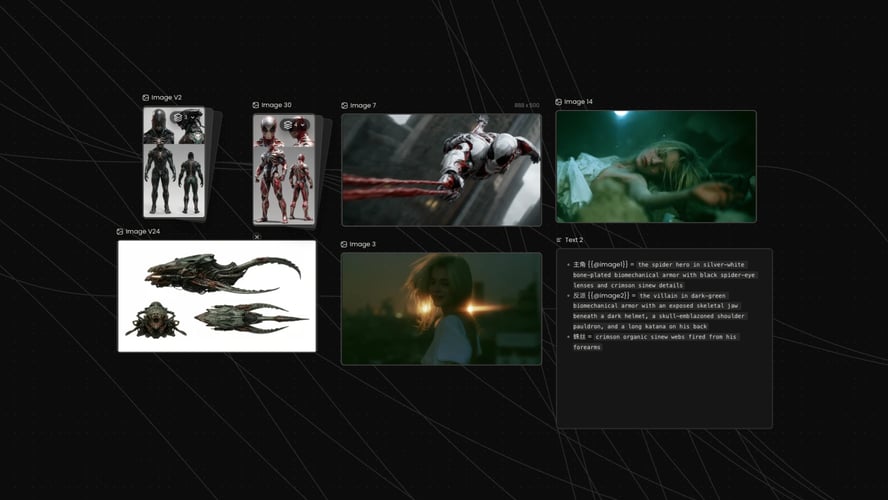 단계 02
동작을 순서대로 작성하세요. 무엇이 먼저 일어나는지, 장면이 어떻게 변하는지, 카메라가 무엇을 하는지, 클립이 어떻게 마무리되는지 설명하세요.
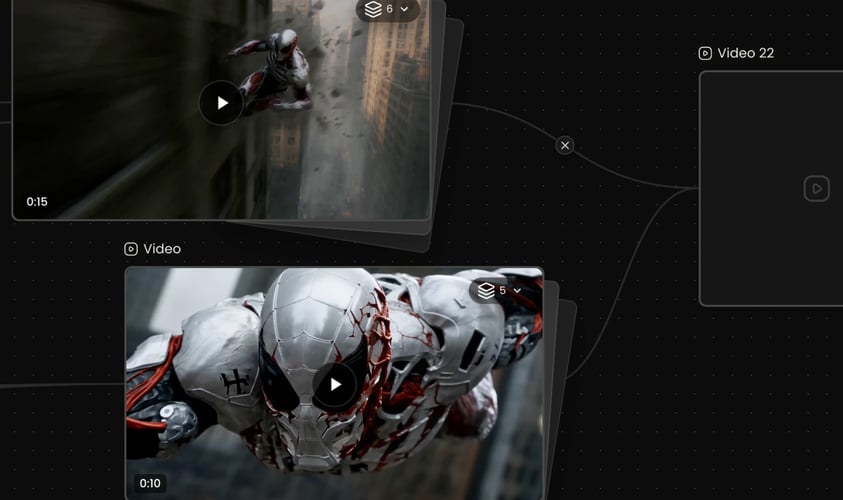 단계 03
Buzzy 작업 공간에서 사용 가능한 설정을 선택하고 생성한 뒤 사운드와 함께 전체 결과를 확인하세요.
Buzzy
각 자산이 무엇에 영향을 주어야 하는지 모델에 알려주세요.
안정적인 설명과 일관된 레퍼런스를 사용하세요. 여러 샷에서 알아볼 수 있게 유지되어야 할 핵심 특징을 명시하세요.
읽기 쉬운 시작과 결과가 있는 동작을 작성하세요.
각 샷마다 주요 카메라 동작을 하나씩 선택하세요.
공통된 피사체와 시각적 언어를 공유하는 몇 개의 비트로 시퀀스를 나누세요.
시각적 타임라인과 관련해 분위기, 효과음, 대사 맥락, 음악을 설명하세요.
Seedance 2.0은 짧은 멀티샷 생성을 지원하며, 활성화된 길이, 비율, 출력 옵션이 Buzzy 내에 표시됩니다.
완성된 클립을 검토하고 다음 변경 사항을 분리하세요.
한 명의 캐릭터나 하나의 사건을 중심으로 짧은 설정, 동작, 해결을 구성하세요.
리빌, 시연, 라이프스타일 장면 또는 캠페인 스토리보드를 만드세요.
오디오를 사용해 페이스, 움직임, 분위기를 이끄세요. 어떤 동작이 리듬에 반응해야 하는지, 장면이 어디에서 바뀌는지 설명하세요. Seedance 2.
선택한 소셜 형식에 맞춰 즉각적인 후크, 읽기 쉬운 변형 또는 간결한 동작 시퀀스를 디자인하세요.
Buzzy는 여러 영상 모델과 창의적인 워크플로를 한곳에 모읍니다.
일반적인 Seedance 2.0 질문에 대한 답변입니다.
Seedance 2.0은 ByteDance Seed의 멀티모달 AI 영상 모델입니다.
모델을 선택하고 관련 레퍼런스를 추가한 뒤 주제, 시퀀스, 모션, 카메라, 사운드 연출을 작성하세요.
네. 오디오는 멀티모달 입력의 일부가 될 수 있으며 리듬, 분위기 또는 사운드 연출을 이끌 수 있습니다. 오디오가 시각적 시퀀스와 어떻게 연관되는지 설명하세요.
네. 이 모델은 멀티샷 오디오-영상 생성을 지원합니다. 오프닝, 전개, 해결이 있는 간결한 시퀀스를 계획하세요. 프롬프트가 의도적으로 변화를 주지 않는 한 피사체와 시각적 스타일을 안정적으로 유지하세요.
이 모델은 텍스트, 이미지, 영상, 오디오 입력을 지원합니다. 각 레퍼런스를 명확한 목적에 맞게 사용하고 세트를 일관되게 유지하세요.
Seedance 2.0은 복잡한 움직임, 물리적 사실감, 제어성을 위해 설계되었습니다.
이 모델은 영상 편집 및 확장 워크플로를 지원합니다. 소스 맥락을 제공하고 변경되지 않아야 할 부분을 명시한 뒤 새로운 동작이나 눈에 보이는 편집을 설명하세요.
Buzzy는 현재 접근 권한, 모델 사용 가능 여부, 크레딧 요건, 설정을 작업 공간 내에 표시합니다.
Turn text, images, video, and audio references into a connected video sequence. Seedance 2.0 is built around unified multimodal audio-video generation, giving creators a way to direct subject motion, camera behavior, scene structure, and sound in the same brief. Buzzy places that capability inside a focused creative workspace. Start with the idea you need to communicate and the source material that protects it. A text prompt can create a new scene, while visual or audio references can guide identity, motion, framing, rhythm, and atmosphere. Seedance 2.0 is especially useful when the concept needs controllable movement and synchronized sound across more than one shot.
Use the medium that best communicates each part of the idea. Text explains the objective and sequence. Images can establish characters, products, compositions, or style. Video can provide motion and camera context. Audio can guide rhythm, ambience, or the intended soundscape. Seedance 2.0 reasons across these inputs as parts of one creative request.
Plan several connected shots instead of generating unrelated clips. Define the opening, progression, transition, and ending. Seedance 2.0 supports multi-shot output with synchronized audio, allowing the story and sound to develop together. Keep the sequence concise enough that every shot has a distinct purpose.
Describe how subjects move through the environment and how the camera responds. Seedance 2.0 is designed for complex motion, physical accuracy, realism, and controllability. Separate subject action from camera action, and state the timing when one movement depends on another.
Use source material to continue a scene, reshape an action, or develop a new version that remains connected to the original. Seedance 2.0 supports editing and extension workflows. Explain what must stay stable and identify the requested change instead of asking the model to reinvent the entire sequence.
Choose Seedance 2.0 in Buzzy and decide whether the concept begins with text alone or needs image, video, or audio references. Use only assets that belong to the same creative direction. Identify the core subject, visual anchor, or sound cue that should remain recognizable throughout the sequence.
Write the action in order. State what happens first, how the scene changes, what the camera does, and how the clip resolves. Add sound direction that belongs to the same timeline. Seedance 2.0 can combine multiple modalities, but the prompt should still make their relationships explicit.
Choose the settings available in the Buzzy workspace, generate, and watch the full result with sound. Review subject consistency, motion quality, camera continuity, transitions, and audio. Preserve the parts that worked and revise the most important issue. Controlled iteration is easier to evaluate than replacing the whole brief after every take.
Tell the model what each asset should influence. One image may define a person, another a location, a video may provide a motion pattern, and audio may establish pacing. Seedance 2.0 supports multiple reference types, but a clear hierarchy prevents one asset from unintentionally overriding another.
Use stable descriptions and cohesive references. Name the defining features that must remain recognizable across shots. If the subject changes clothing, location, or state during the sequence, describe when that transformation occurs. Consistency improves when change is deliberate rather than implied.
Write actions with a readable beginning and result. Explain contact, weight, direction, and timing when they matter: a hand lifts an object, fabric reacts to movement, water splashes after impact, or a vehicle changes speed before turning. Seedance 2.0 is designed for realistic and controllable motion, but the brief should still be physically understandable.
Choose one primary camera behavior for each shot. A tracking move follows action, a push-in directs attention, a reveal changes context, and a static view makes transformation easier to see. Do not stack conflicting instructions. The camera should help the audience understand the moment.
Divide the sequence into a few beats with a shared subject and visual language. Each shot should introduce information or advance the action. Use transition language when the connection matters. Seedance 2.0 can produce multi-shot video, but structure still comes from the brief.
Describe ambience, effects, dialogue context, or music in relation to the visual timeline. The model supports audio-video joint generation and advanced audio output, but generated sound requires review. Check speech, synchronization, loudness, and whether audio matches the environment before publishing.
Seedance 2.0 supports short multi-shot generation, with active duration, ratio, and output options shown inside Buzzy. Choose the format for the final destination before writing the composition. A vertical clip needs tighter subject framing than a landscape sequence.
Review the complete clip and isolate the next change. If motion works but the audio is wrong, keep the visual direction stable and revise the sound. If the subject is consistent but the transition feels abrupt, change the shot connection. One controlled decision per pass makes improvement easier to trace.
Build a short setup, action, and resolution around one character or event. Use images to define identity, video references for motion, and text to explain how the shots connect. Seedance 2.0 can support the sequence as one audio-visual idea rather than a set of disconnected clips.
Create a reveal, demonstration, lifestyle scene, or campaign storyboard. Preserve the product’s defining visual details and describe how it moves through the sequence. Use camera changes to reveal context or features, while sound supports the product moment without overwhelming it.
Use audio to guide pacing, movement, and atmosphere. Explain which motions should respond to the rhythm and where the scene changes. Seedance 2.0 can work with audio references and joint generation, making it useful for performance concepts, music-led visuals, and rhythmic transitions.
Design an immediate hook, a readable transformation, or a compact action sequence for a chosen social format. Keep the primary subject visible on a small screen and make the first beat clear. References can guide style, but the prompt should still define the intended story or change.
Seedance 2.0 is ByteDance Seed’s multimodal AI video model. It accepts text, image, audio, and video inputs and is designed for unified audio-video generation, complex motion, controllability, multi-shot sequences, editing, and extension.
Select the model, add the relevant references, and write the subject, sequence, motion, camera, and sound direction. Choose the available format and duration settings, generate the result, and review visual continuity and audio together before making a focused revision.
Yes. Audio can be part of the multimodal input and can guide rhythm, atmosphere, or sound direction. Explain how the audio relates to the visual sequence. Review the generated sound and synchronization because output can vary from the intended reference.
Yes. The model supports multi-shot audio-video generation. Plan a concise sequence with an opening, progression, and resolution. Keep subjects and visual style stable unless the prompt intentionally introduces a change.
The model supports text, image, video, and audio inputs. Use each reference for a defined purpose and keep the set coherent. The exact upload limits and options available to you should be taken from the active Buzzy workspace.
Seedance 2.0 is designed for complex movement, physical realism, and control. Better prompts still explain the action in time: what begins the motion, how the subject and environment respond, what the camera does, and where the action ends.
The model supports video editing and extension workflows. Provide the source context, state what must remain unchanged, and describe the new action or visible edit. Keep each request focused so the result can be compared directly with the original.
Buzzy displays current access, model availability, credit requirements, and settings inside the workspace. These conditions can change, so use the active interface as the source of truth rather than assuming a permanent free tier.
명확한 오디오-비주얼 아이디어 하나를 Buzzy로 가져와 가장 중요한 요소를 지키는 레퍼런스를 선택하고 시퀀스를 직접적으로 설명하세요.